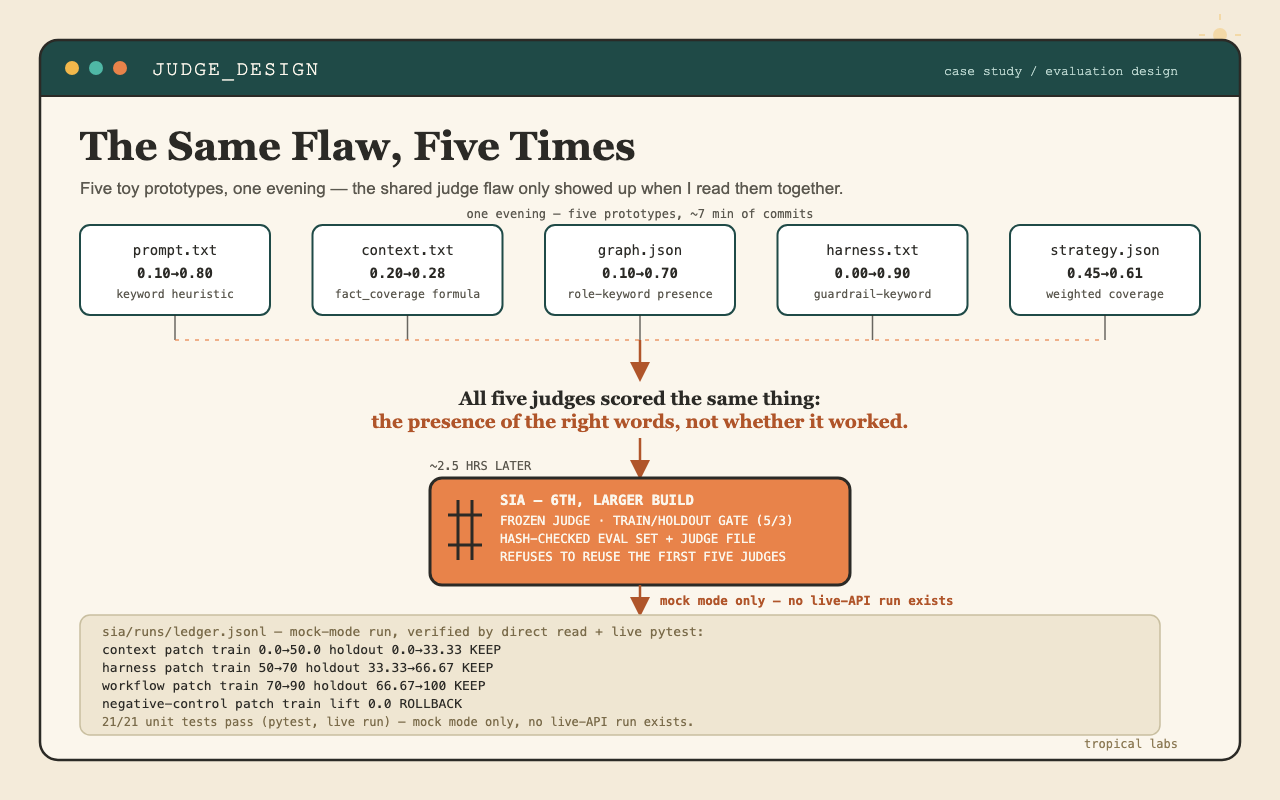
A Frozen Judge, a Holdout Split, and a Hash Check: What It Actually Takes to Trust an Eval Loop
If you're building any kind of optimization loop over LLM-generated artifacts (prompt search, RAG context tuning, agent config search, an auto-eval pipeline that mutates and re-scores), the part of th
Sep 17, 20269 min read4